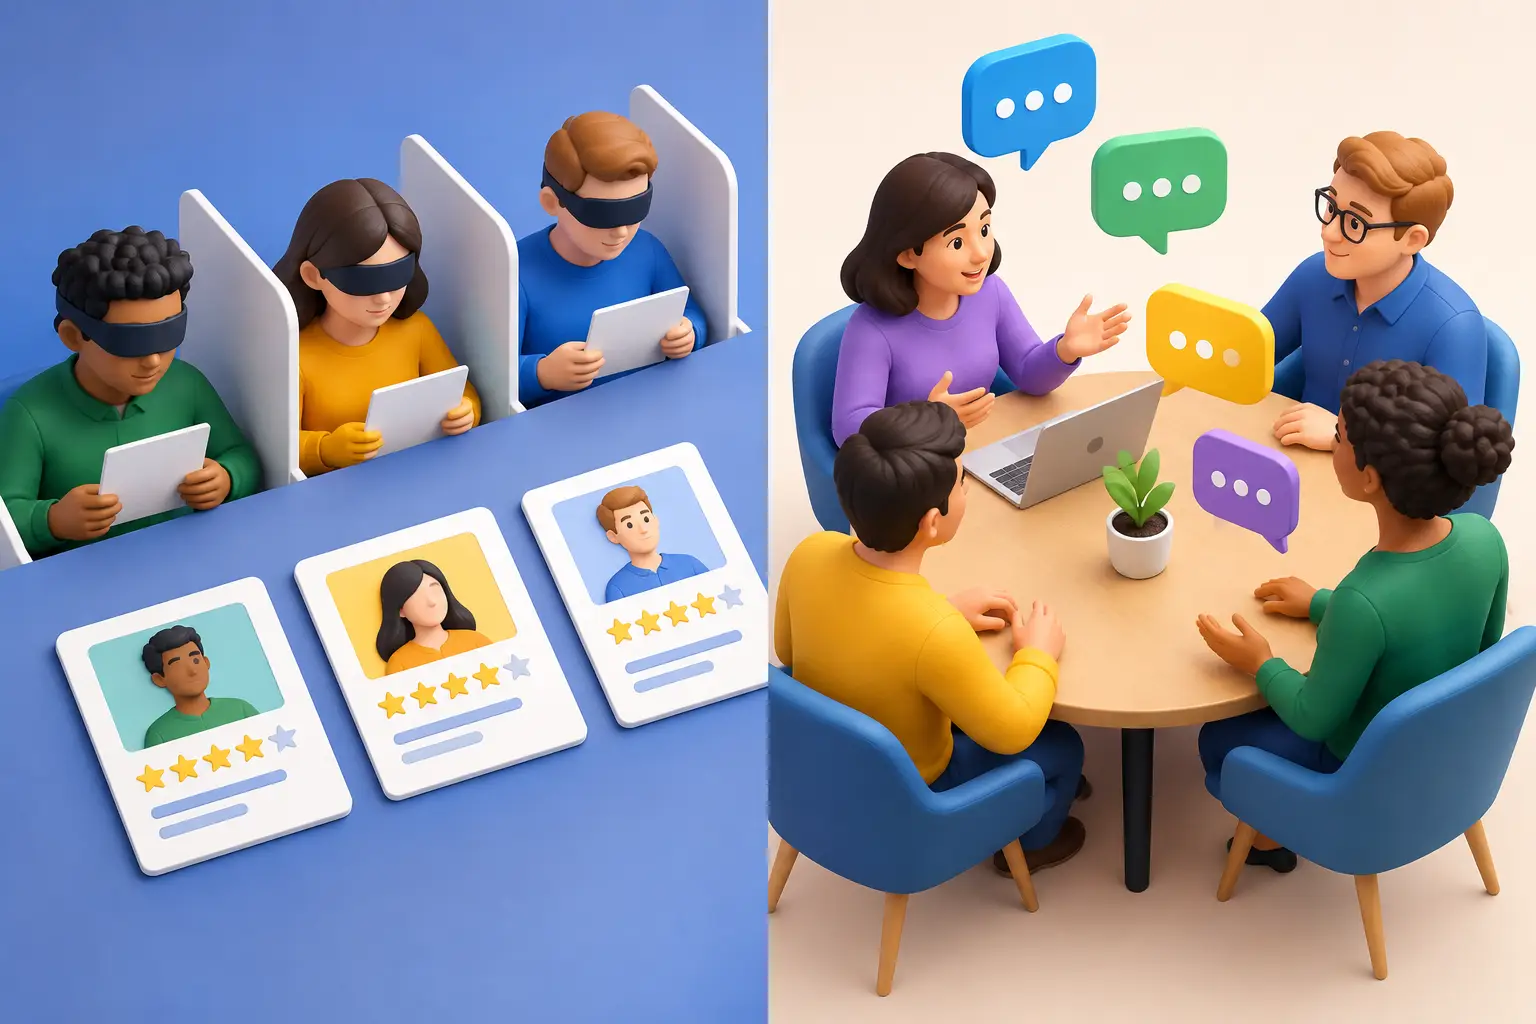
A manager who can see an employee’s self-assessment before submitting their own assessment is no longer assessing independently. Even with good intent, the employee’s language, confidence and examples can shift what the manager notices, discounts or repeats. That is the operational difference at the centre of blind assessments vs open feedback: one protects independent judgement during evaluation; the other makes input visible as the conversation develops.
For HR teams, this is not a minor workflow choice. It affects the consistency of ratings, the quality of manager-employee discussions, and how defensible performance decisions are when results are compared across a team.
Blind Assessments vs Open Feedback: The Core Difference
A blind assessment is a controlled submission process. The employee and manager complete their assessments against the same role expectations, goals or tasks, but neither can view the other’s responses until both have submitted. The system then presents the results side by side, making agreement, gaps and evidence visible for discussion.
Open feedback works differently. One party can see feedback, ratings or comments as they are entered, or before they submit their own view. This may happen in shared documents, conventional review platforms, comment threads, or meetings where self-assessment and manager assessment are completed collaboratively.
Neither approach is universally right. The correct choice depends on what the organisation is trying to achieve at that point in the process. If the objective is to gather independent evidence and reduce premature influence, blind assessment is stronger. If the objective is rapid coaching, problem-solving or recognition, open feedback can be more useful.
The mistake is treating these as interchangeable. Evaluation and coaching require different controls.
Blind does not mean anonymous
Blind assessments are sometimes confused with anonymous feedback. They are not the same. In a manager-employee review, both people generally know who is participating. What remains hidden is the content of each assessment until submission is complete.
That distinction matters. Anonymous feedback can protect respondents in sensitive situations, but it can also reduce accountability and make follow-up harder. Blind submission preserves accountability while preventing one person’s draft from becoming the reference point for the other.
Why Open Feedback Can Distort Performance Reviews
Open feedback feels transparent, and transparency is often valuable. But visibility before independent assessment introduces several predictable effects.
First, it creates anchoring. A manager who reads an employee’s detailed self-rating may unconsciously adjust their own judgement towards it, particularly where evidence is mixed or the manager has limited day-to-day visibility. The opposite can happen as well: an employee who sees a manager’s early assessment may soften their own account rather than document work they believe has been overlooked.
Second, open workflows can reward confidence over contribution. A well-written self-assessment can appear more persuasive than a concise one, even where both employees delivered comparable outcomes. This is particularly relevant for technical, operational and client-facing roles where the most important work is not always the most visible work.
Third, open review forms blur the line between a record of performance and a negotiation about performance. Constructive discussion should follow the assessment. When it happens before both views are captured, the final record can reflect who framed the discussion first rather than the clearest assessment of role delivery.
These risks increase when managers use inconsistent criteria. If one manager assesses broad attitude and another assesses task-level outcomes, a visible self-review will not fix the underlying problem. It may simply make the inconsistency harder to identify.
Where Open Feedback Belongs
Open feedback should not be removed from performance management. It should be used deliberately.
It is effective for ongoing check-ins, project retrospectives, development planning and recognition. In these settings, the goal is not to establish an independent rating. The goal is to clarify expectations, address barriers and agree on next actions. Visibility can accelerate that work.
For example, a manager and employee may openly review progress against a development goal, identify a capability gap, and agree on training or stretch work. There is little value in hiding those observations if the conversation is about support rather than formal evaluation.
Open feedback is also appropriate after blind assessments have been released. Once both perspectives are recorded, the side-by-side view gives the conversation a stronger starting point. The manager can ask why an employee rated a responsibility differently, examine the evidence, and document an agreed focus area without rewriting history.
The sequence matters: independent assessment first, open discussion second.
Build Blind Assessments Around the Actual Role
Blind submission alone does not produce a fair review. It only protects the independence of the inputs. The assessment itself still needs to be anchored to clear, relevant criteria.
Generic prompts such as “demonstrates leadership” or “meets expectations” leave too much room for interpretation. Managers will apply them differently, and employees will respond with different assumptions about what good performance looks like. That makes calibration difficult before the review discussion has even begun.
A more reliable design starts with the position description and translates it into observable responsibilities. What is the employee accountable for? Which tasks, standards, outcomes or stakeholder commitments define successful performance? What evidence would show that the work was completed well, inconsistently or not at all?
This is where AI-assisted role analysis can improve review quality. Rather than asking managers to build every assessment from a blank form, software can extract role responsibilities from existing position descriptions and organise them into structured assessment areas. The manager still applies judgement, but that judgement is directed at work that belongs to the role.
CALIBRATE applies this logic by pairing AI-extracted responsibilities with structured self and manager assessments, then holding results until both parties submit. The resulting comparison gives managers a practical view of where perceptions align and where a discussion is required.
Use rating scales that produce usable evidence
A rating scale should describe performance against expectations, not personality. Labels need clear definitions, and managers need enough guidance to distinguish between occasional success, consistent delivery and sustained performance above the role standard.
Comments matter as well, but they should support the rating rather than replace it. A manager who selects a score without evidence has not created a calibrated assessment. Equally, a long comment that does not address the relevant responsibility creates administrative volume, not clarity.
For high-stakes decisions, ask for specific examples where ratings are materially above or below expectations. This focuses manager attention on evidence without forcing lengthy written justifications for every routine item.
How to Introduce a Blind Review Workflow
The change should be explained as a process control, not as a sign that management distrusts employees or managers. The message is straightforward: both perspectives are valuable, and each should be captured before either is influenced by the other.
Start with one review cycle or one business unit if the organisation has inconsistent review practices. Use a common set of role-based criteria, set a submission deadline, and make clear that neither assessment can be edited after the lock point without an auditable reopening process. Then release results for the review meeting.
Manager preparation is essential. Managers should understand that a gap between self and manager ratings is not automatically a problem to correct. It is a discussion prompt. A large gap may reveal unclear expectations, poor visibility of work, different interpretations of quality, or a genuine performance issue. Treating every difference as employee overconfidence produces defensive conversations and wastes the value of the comparison.
HR should also review patterns across teams. If one manager’s ratings are consistently lower than peer managers for comparable responsibilities, that may point to a calibration issue. If employees repeatedly rate one responsibility lower than managers do, the organisation may have a communication or workload problem that individual reviews alone will not solve.
The Trade-off: Control Versus Immediate Collaboration
Blind assessments add a small amount of process discipline. Participants cannot resolve differences while drafting, and review meetings need to be scheduled after both submissions are complete. In fast-moving teams, that can feel slower than a shared document.
The benefit is cleaner input. Organisations gain a record of what each party believed before the discussion shaped the outcome. That improves calibration, creates more focused manager conversations and reduces the risk that ratings are driven by confidence, timing or influence.
Open feedback remains valuable where collaboration is the point. Blind assessment is stronger where independent judgement is the point. A mature performance process does not choose one method for every interaction. It applies the right control at the right stage.
When designing the next review cycle, begin with a practical question: do you need participants to reach a shared view now, or do you first need to understand where their views genuinely differ? The answer should determine whether feedback stays open or assessments stay blind.